
  ██╗  ██╗███████╗ █████╗ ██████╗ ██████╗  ██████╗  ██████╗ ███╗   ███╗
  ██║  ██║██╔════╝██╔══██╗██╔══██╗██╔══██╗██╔═══██╗██╔═══██╗████╗ ████║
  ███████║█████╗  ███████║██║  ██║██████╔╝██║   ██║██║   ██║██╔████╔██║
  ██╔══██║██╔══╝  ██╔══██║██║  ██║██╔══██╗██║   ██║██║   ██║██║╚██╔╝██║
  ██║  ██║███████╗██║  ██║██████╔╝██║  ██║╚██████╔╝╚██████╔╝██║ ╚═╝ ██║
  ╚═╝  ╚═╝╚══════╝╚═╝  ╚═╝╚═════╝ ╚═╝  ╚═╝ ╚═════╝  ╚═════╝ ╚═╝     ╚═╝
              The context compression layer for AI agents
60–95% fewer tokens (for JSON data), 15-20% fewer tokens (for coding agents) · library · proxy · MCP · content-aware compressors · local-first · reversible




Docs ·
Install ·
Proof ·
Agents ·
Discord ·
AI agents / LLMs: read /llms.txt here, or fetch the live index / full docs blob.
Headroom compresses everything your AI agent reads — tool outputs, logs, RAG chunks, files, and conversation history — before it reaches the LLM. Same answers, fraction of the tokens.
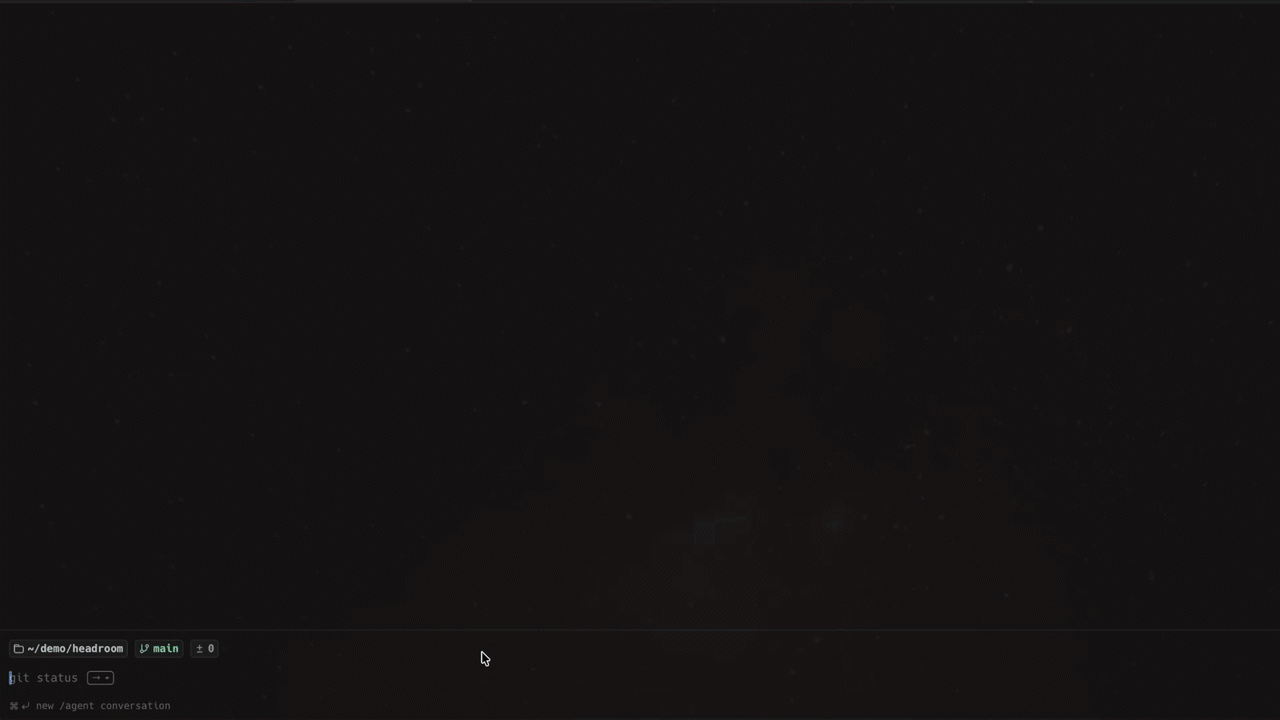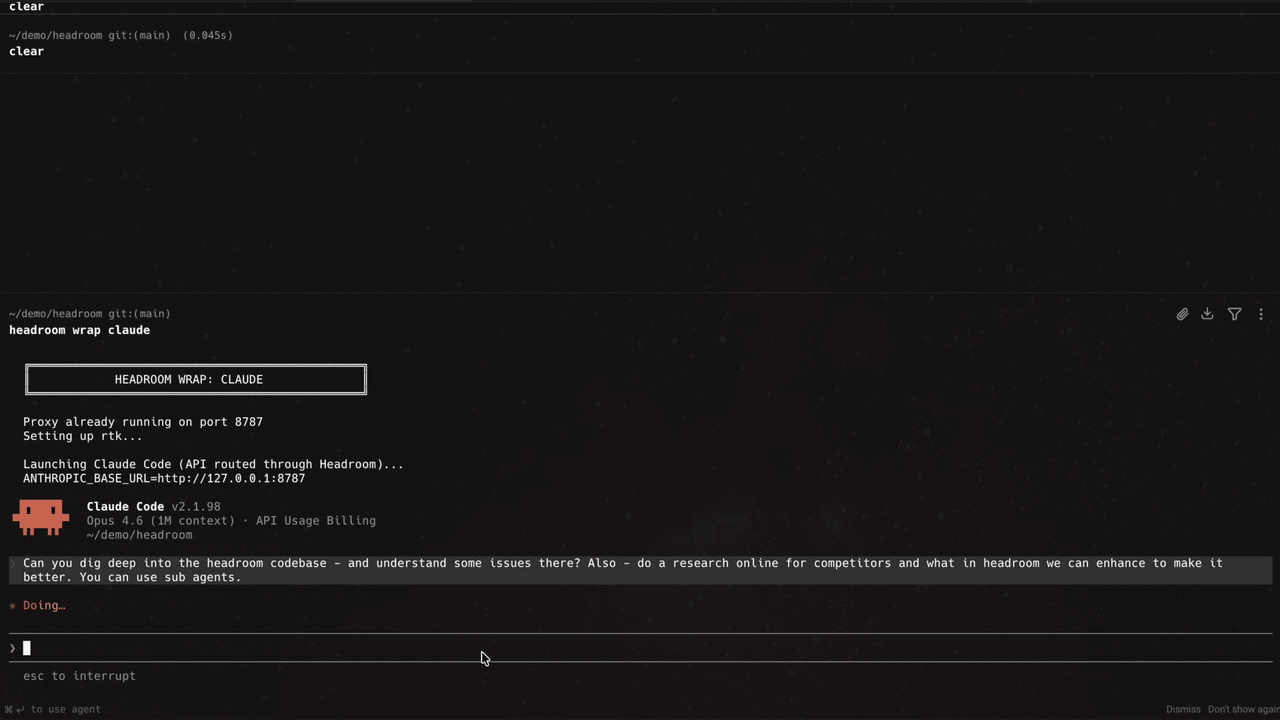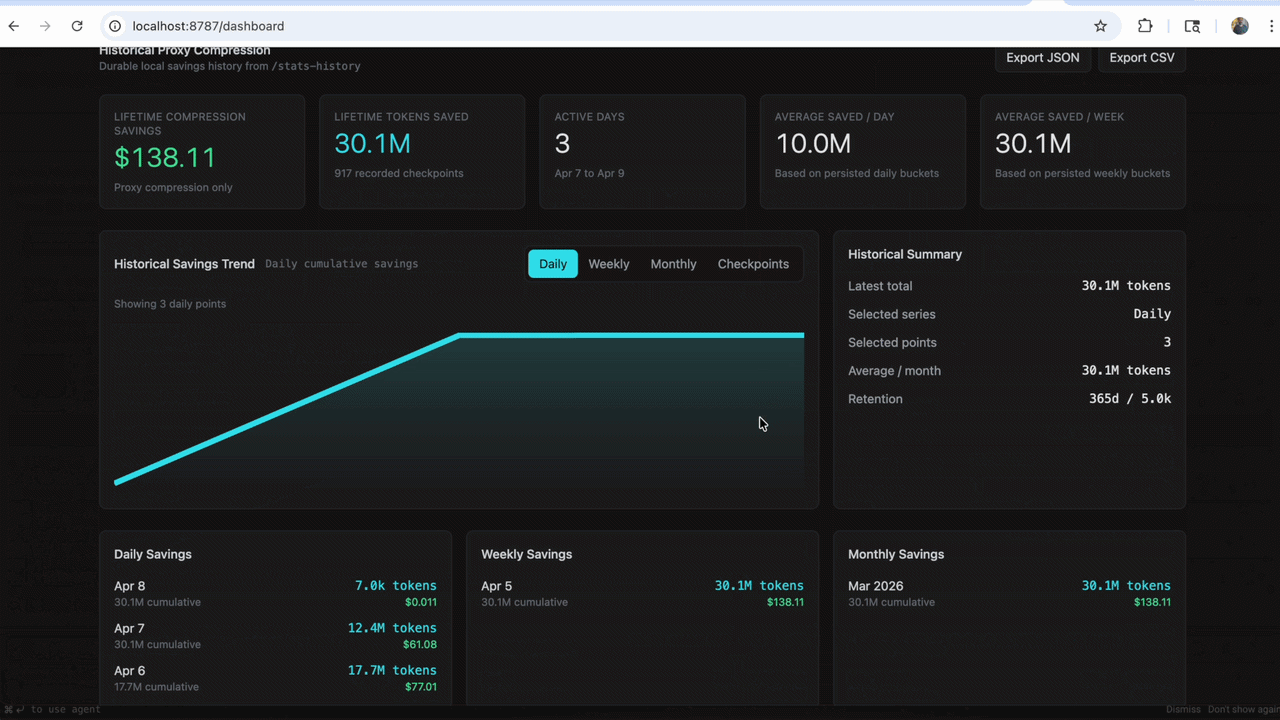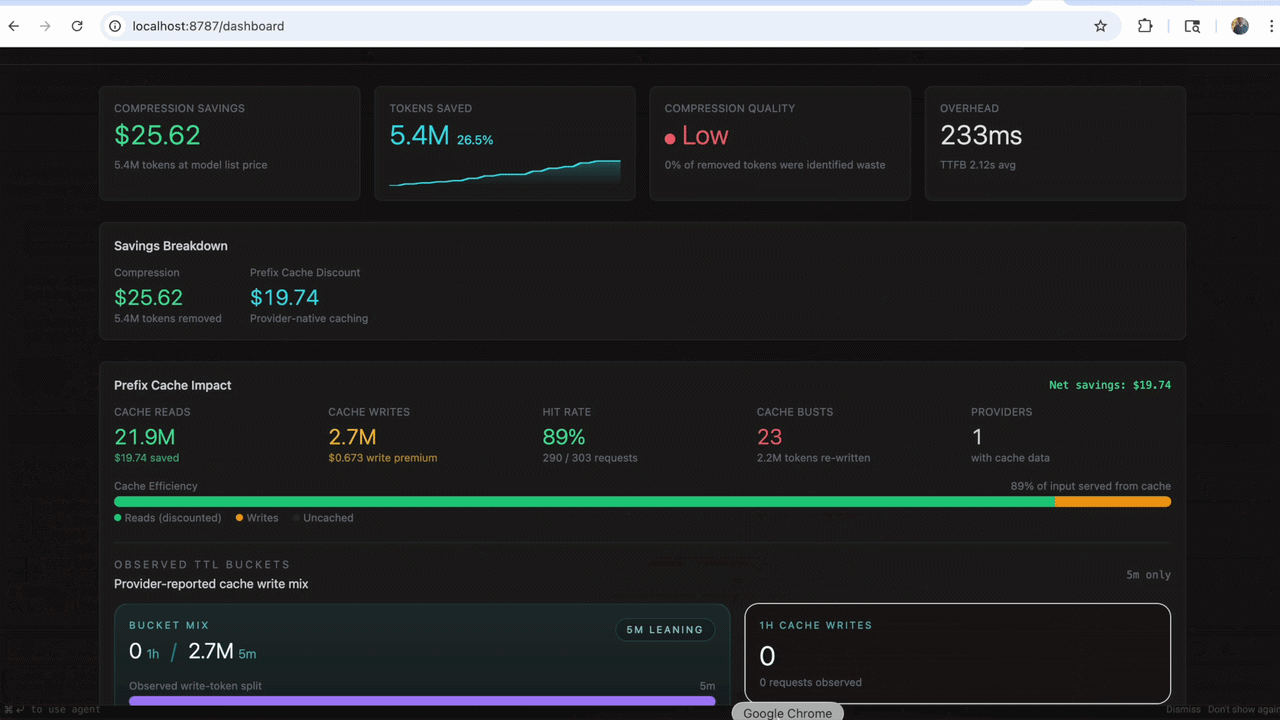
Live: 10,144 → 1,260 tokens — same FATAL found.