
LLM inference, optimized for your Mac
Continuous batching and tiered KV caching, managed directly from your menu bar.


Install · Quickstart · Features · Models · CLI Configuration · Benchmarks · oMLX.ai
English ·
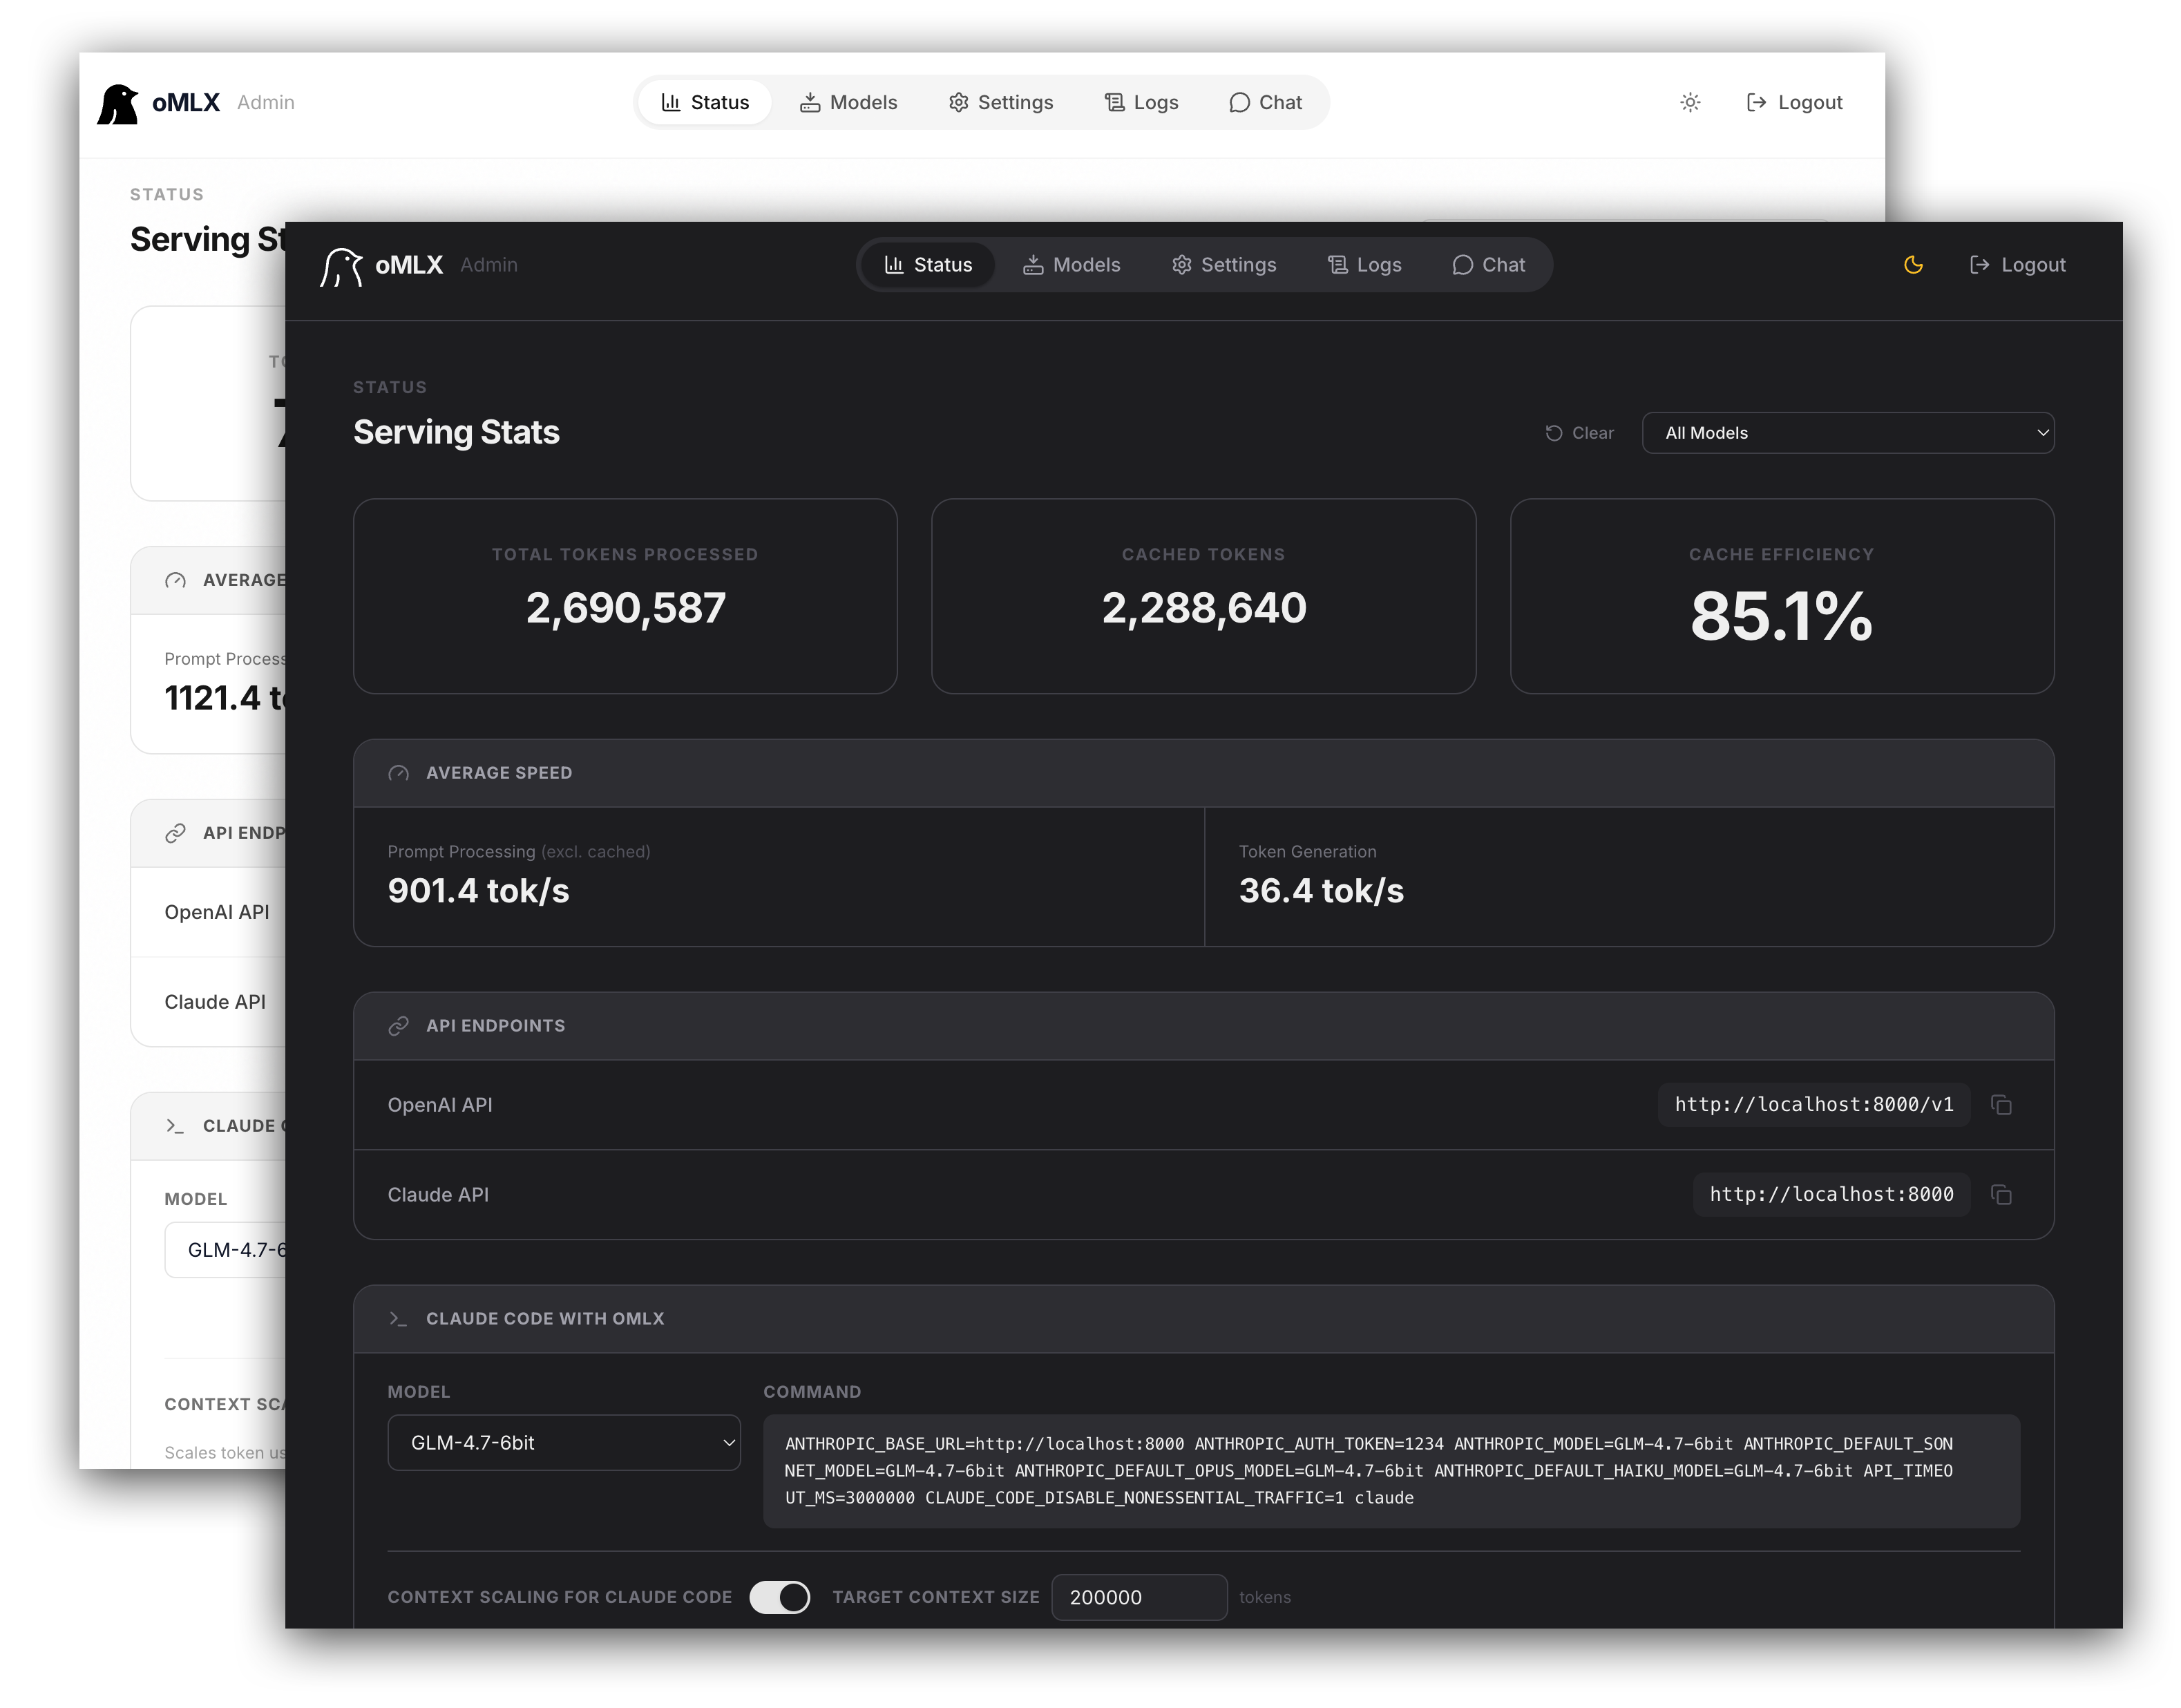
Every LLM server I tried made me choose between convenience and control. I wanted to pin everyday models in memory, auto-swap heavier ones on demand, set context limits - and manage it all from a menu bar.
oMLX persists KV cache across a hot in-memory tier and cold SSD tier - even when context changes mid-conversation, all past context stays cached and reusable across requests, making local LLMs practical for real coding work with tools like Claude Code. That's why I built it.